In 2020 when A100 was launched by Nvidia. If someone asked what GPU to use for inference, the A100 was our default answer. It was not a bad recommendation at the time. It was genuinely one of the best data center GPUs available, and for a few years there was not a clearly better option built specifically for serving models rather than training them.
That stopped being true a while ago, and we stopped recommending the A100 as a default for inference because of it. Let me walk through exactly why, and what changed.
Why was the A100 the default inference recommendation for so long?
Because it was launched in 2020, and for the next few years, nothing purpose-built for inference genuinely outperformed it on a cost and capability basis. The A100 was a versatile, capable workhorse, strong at both training and inference, and in the absence of anything better suited specifically to inference, it became the default answer for both.
Launched in 2020 on the Ampere architecture
Built as a general-purpose data center accelerator, not optimized specifically for either training or inference
Remained the strongest realistic option for years simply because nothing more inference-focused had arrived yet
Was the A100 ever actually built specifically for inference?
No, and this is the part that gets overlooked. The A100 was designed as a broad, capable accelerator meant to handle training and inference reasonably well, at a time before inference workloads had their own dedicated hardware category. It did the job because it was the best available tool, not because it was purpose-built for the job.
What actually changed after 2023?
The L4 launched, and it was built with a fundamentally different goal in mind. Rather than trying to be a strong generalist, it was designed specifically around efficient inference.
Built on the newer Ada Lovelace architecture, with native FP8 support the A100 does not have
24GB of GDDR6 memory, comfortably enough for the model sizes most production inference workloads actually run
A 72W TDP, a fraction of the A100's power draw, without sacrificing the throughput that inference workloads actually need
What made the L4 the right balance for inference specifically?
Technically, it lines up almost perfectly with what most real inference workloads need. Most production inference happens on models somewhere in the 7B to 30B parameter range, not the largest models available, and the L4's memory and bandwidth comfortably cover that range. On the budget side, it does this at a fraction of the A100's hourly cost and power draw, which matters just as much once you are running inference continuously rather than as an occasional workload.
How do the A100 and L4 actually compare once you line them up for inference?
Here is the honest side by side.
Spec
A100 (80GB)
L4
Launch year
2020
2023
Architecture
Ampere
Ada Lovelace
VRAM
80GB HBM2e
24GB GDDR6
Memory bandwidth
Roughly 2,039 GB/s
300 GB/s
TDP
400W
72W
Native FP8 support
No
Yes
Built primarily for
General purpose, training and inference
Inference specifically
Does the A100 lose on every metric, or does it still win somewhere?
It still wins comfortably on raw memory and bandwidth, which matters for genuinely large models or heavy training workloads. If your job actually needs 80GB of VRAM or the bandwidth to train efficiently, the A100 remains a real, capable option. What changed is that most inference workloads never needed that much capacity in the first place, and recommending an A100 by default for those workloads meant paying for headroom that was never going to get used.
👉You may like: L4 vs T4 GPUa
Why does power draw matter this much for an inference recommendation?
Because inference, unlike training, tends to run continuously rather than in defined bursts. A 400W card running around the clock adds up in electricity and cooling costs in a way that a single training run does not, and that cost compounds every single day the workload stays live. The L4's 72W draw is not just a smaller number on a spec sheet. It is a meaningfully lower total cost of ownership for anything running in production long term.
So when does the A100 still make sense today?
There are genuine cases where it remains the right call.
Teams that already own A100 hardware and are extending existing capacity rather than provisioning new infrastructure
Large batch training runs where the extra VRAM and bandwidth are actually being used
Workloads that specifically require close to 80GB of memory on a single card
Situations where a smaller card like the L4 genuinely cannot fit the model in question
Outside of these cases, defaulting to the A100 for a new inference deployment usually means paying for capability the workload will never touch.
What do we recommend instead now?
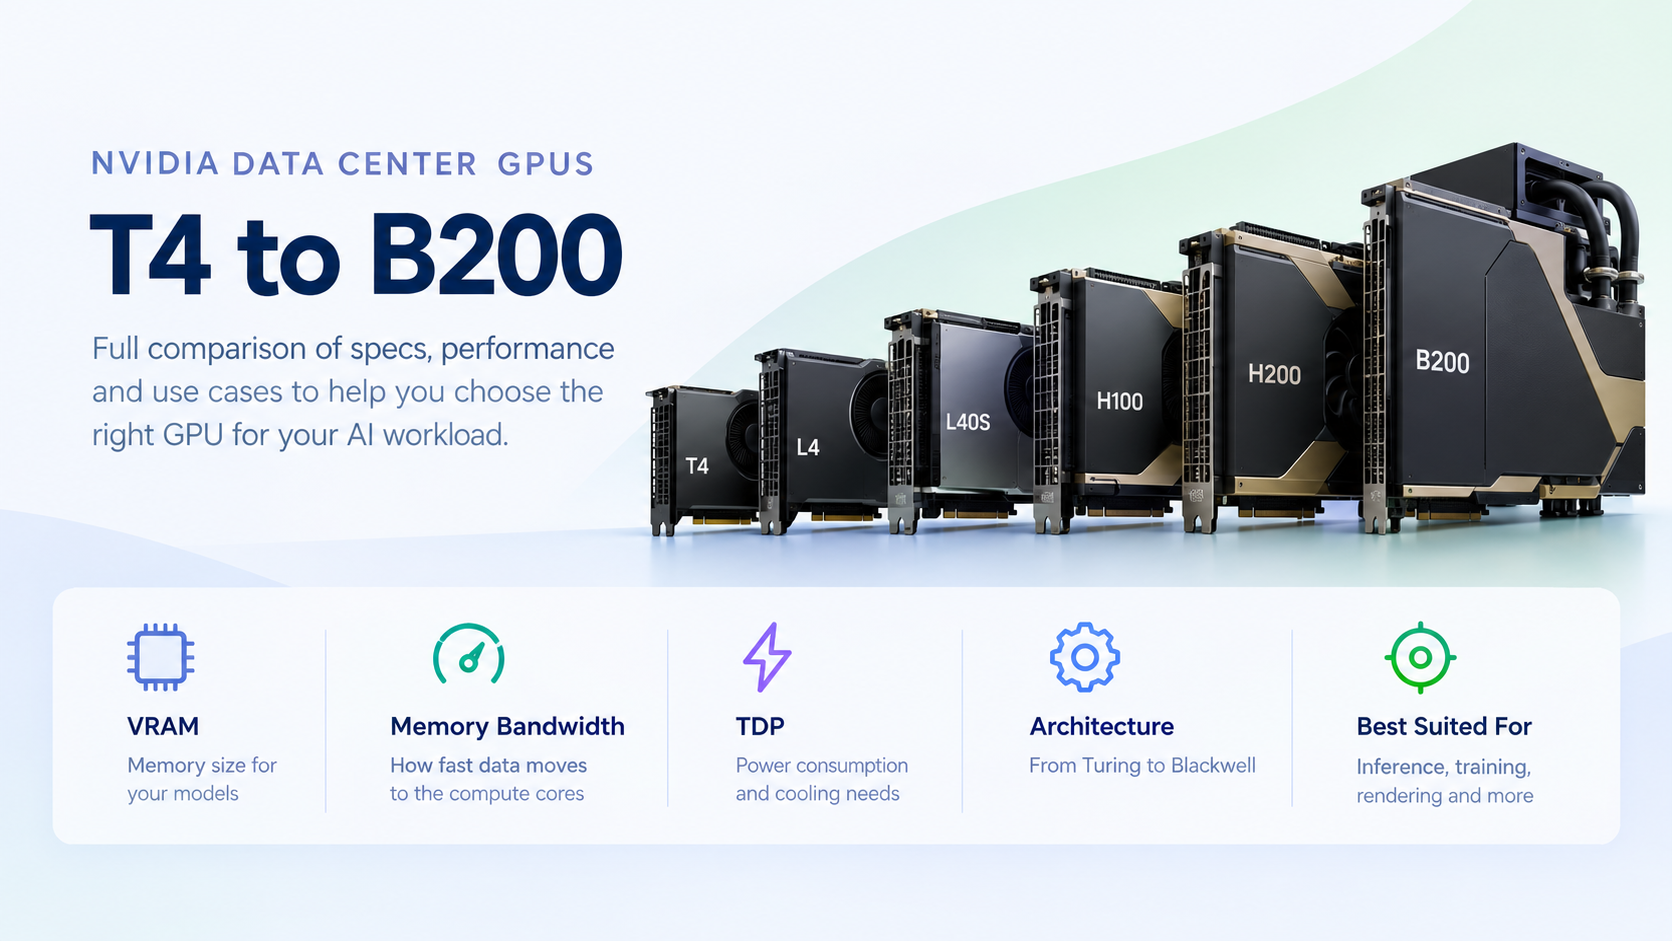
For most inference workloads in the 7B to 30B range, the L4 is our starting recommendation. For workloads that need more headroom than the L4 comfortably provides but do not require a full A100 or H100, the L40S usually fits that gap well. For genuinely large models or high-throughput production serving, H100 or H200 remain the right call, not because they replace the L4, but because they solve a different problem entirely.
The A100 has not disappeared from the conversation. It has simply moved from being the default answer to being the right answer for a much narrower set of situations than it used to
Cover.
A few quick questions people keep asking about this
Is the A100 now considered obsolete for AI workloads generally? Not obsolete, but clearly positioned differently than it was a few years ago. It remains a capable GPU for training and for workloads that genuinely need its memory and bandwidth. It has simply stopped being the right default for standard inference workloads once purpose-built alternatives arrived.
Does this mean the L4 is always the right choice for inference? Not always, but it is the right starting point for most common inference workloads. Once model size or concurrency needs grow past what the L4 comfortably handles, the L40S or a larger GPU becomes the more appropriate choice.
If we already own A100 hardware, should we replace it with L4s? Not necessarily. If the A100 capacity is already paid for and sitting in your infrastructure, using it for existing inference workloads still makes financial sense. The recommendation shift applies mainly to new deployments and new hardware decisions, not to hardware you already own and are actively using.
Where this leaves you
Recommending a GPU by default because it used to be the best all-around option stops making sense once purpose-built alternatives actually fit the job better. The A100 was the right answer for years because nothing better suited to inference existed yet. Once the L4 arrived with the right balance of memory, efficiency, and cost for the workloads most inference deployments actually run, continuing to recommend the A100 by default stopped being the honest answer, and we changed what we tell people accordingly.




 Downloader
 Free FTP



 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek
